
Methodology & Process
From Private and Sovereign AI to Trusted Agentic Action
A Practical Framework for Agentic Transformation
Eastgate Software - German Engineering Standards. Enterprise-Grade Results.
From Private and Sovereign AI to Trusted Agentic Action
A Practical Framework for Agentic Transformation
Keeping control of your data is one decision. Letting an AI agent carry out the next step is another. This paper connects the two: how deployment choices shape what an agent is allowed to do, what evidence to require before production, and how to measure the full cost of a result the business accepts.
 Eastgate Software
Introduction
Putting artificial intelligence (AI) into daily work requires deciding how much control your business needs over the systems it will depend on. Reliance on foreign technology providers raises questions about who operates those systems and protects internal information. An assistant draws on that information to answer a question. A person still decides what to do next.
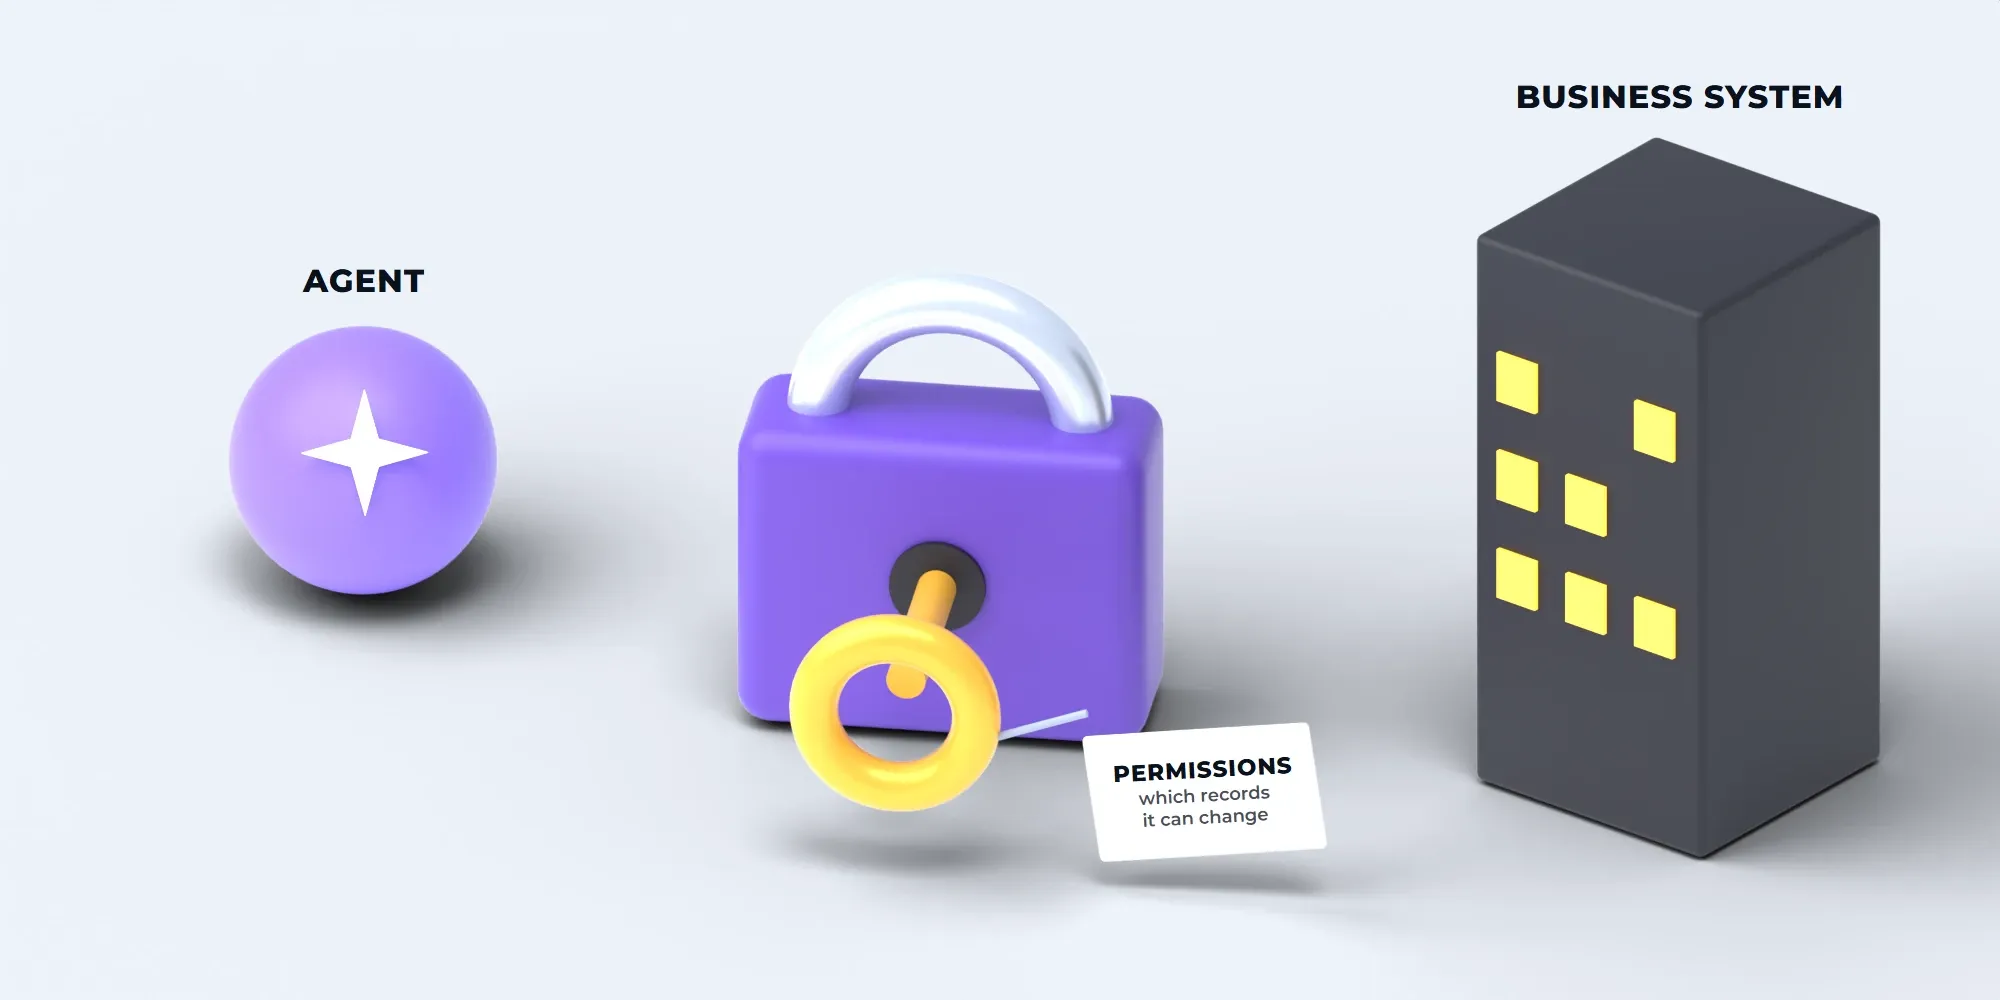
When the system has permission to carry out the next step, the decision changes completely. An AI agent uses a model to choose actions through software tools. Its permissions determine which records it can change. An approval has to apply to the action that actually takes place, and a failed action needs a way back to a person who can resolve it.
The rules protecting internal information must hold as the agent moves from reading to action. Each tool it uses must respect restrictions on where data goes and who can access it. This connects private and sovereign AI with agentic process transformation: the environment must support both the information the agent needs and the work it is allowed to perform.
This paper follows that connection from a useful answer to a business result you can stand behind. Drawing on implementation experience and expert perspectives, it explains how deployment choices shape agent authority, what evidence to require before production, and how to assess the cost of the whole process.
Why are deployment control and process transformation converging?
Choosing an AI provider affects how much control a business keeps over a live workflow. The service determines which model infrastructure the workflow relies on and the options available for processing its data. If changing providers means rebuilding integrations, a supplier change also becomes a process-change project.
Keeping a workable alternative is one way to limit dependence on a supplier. In Europe, the debate about sovereign AI includes interest in alternatives to providers based in the US and China. In September 2026, CNBC reported that Mistral raised €3 billion and described its positioning as a non-US, non-Chinese option amid growing interest in sovereign AI in Europe and elsewhere.
When choosing an AI provider, look at how much control your business will have in practice. Who can access your data? What would it take to switch providers and keep the workflow running? The location of the providers matters, along with who runs the service and what your contract allows.
Control over the service still leaves the business to establish whether the agent will perform its work reliably. For a process owner, that is a practical question: will the workflow follow the required approvals and produce a result the business accepts? Organizations that already run agents in pilots meet the same question when they try to scale. Deloitte's 2026 study of US business leaders measured how widely that concern is shared:
of US leaders piloting agentic AI say an inability to trust and govern agents is a barrier to scaling.
The deployment and the process need to answer these questions together. A rule about where data can go must cover the tools an agent calls, as well as the model itself. The process must then determine what the agent is allowed to do with that information. This gives the business a common set of requirements for choosing its AI environment and designing the work it will perform.
How do you define the control requirement before choosing the platform?
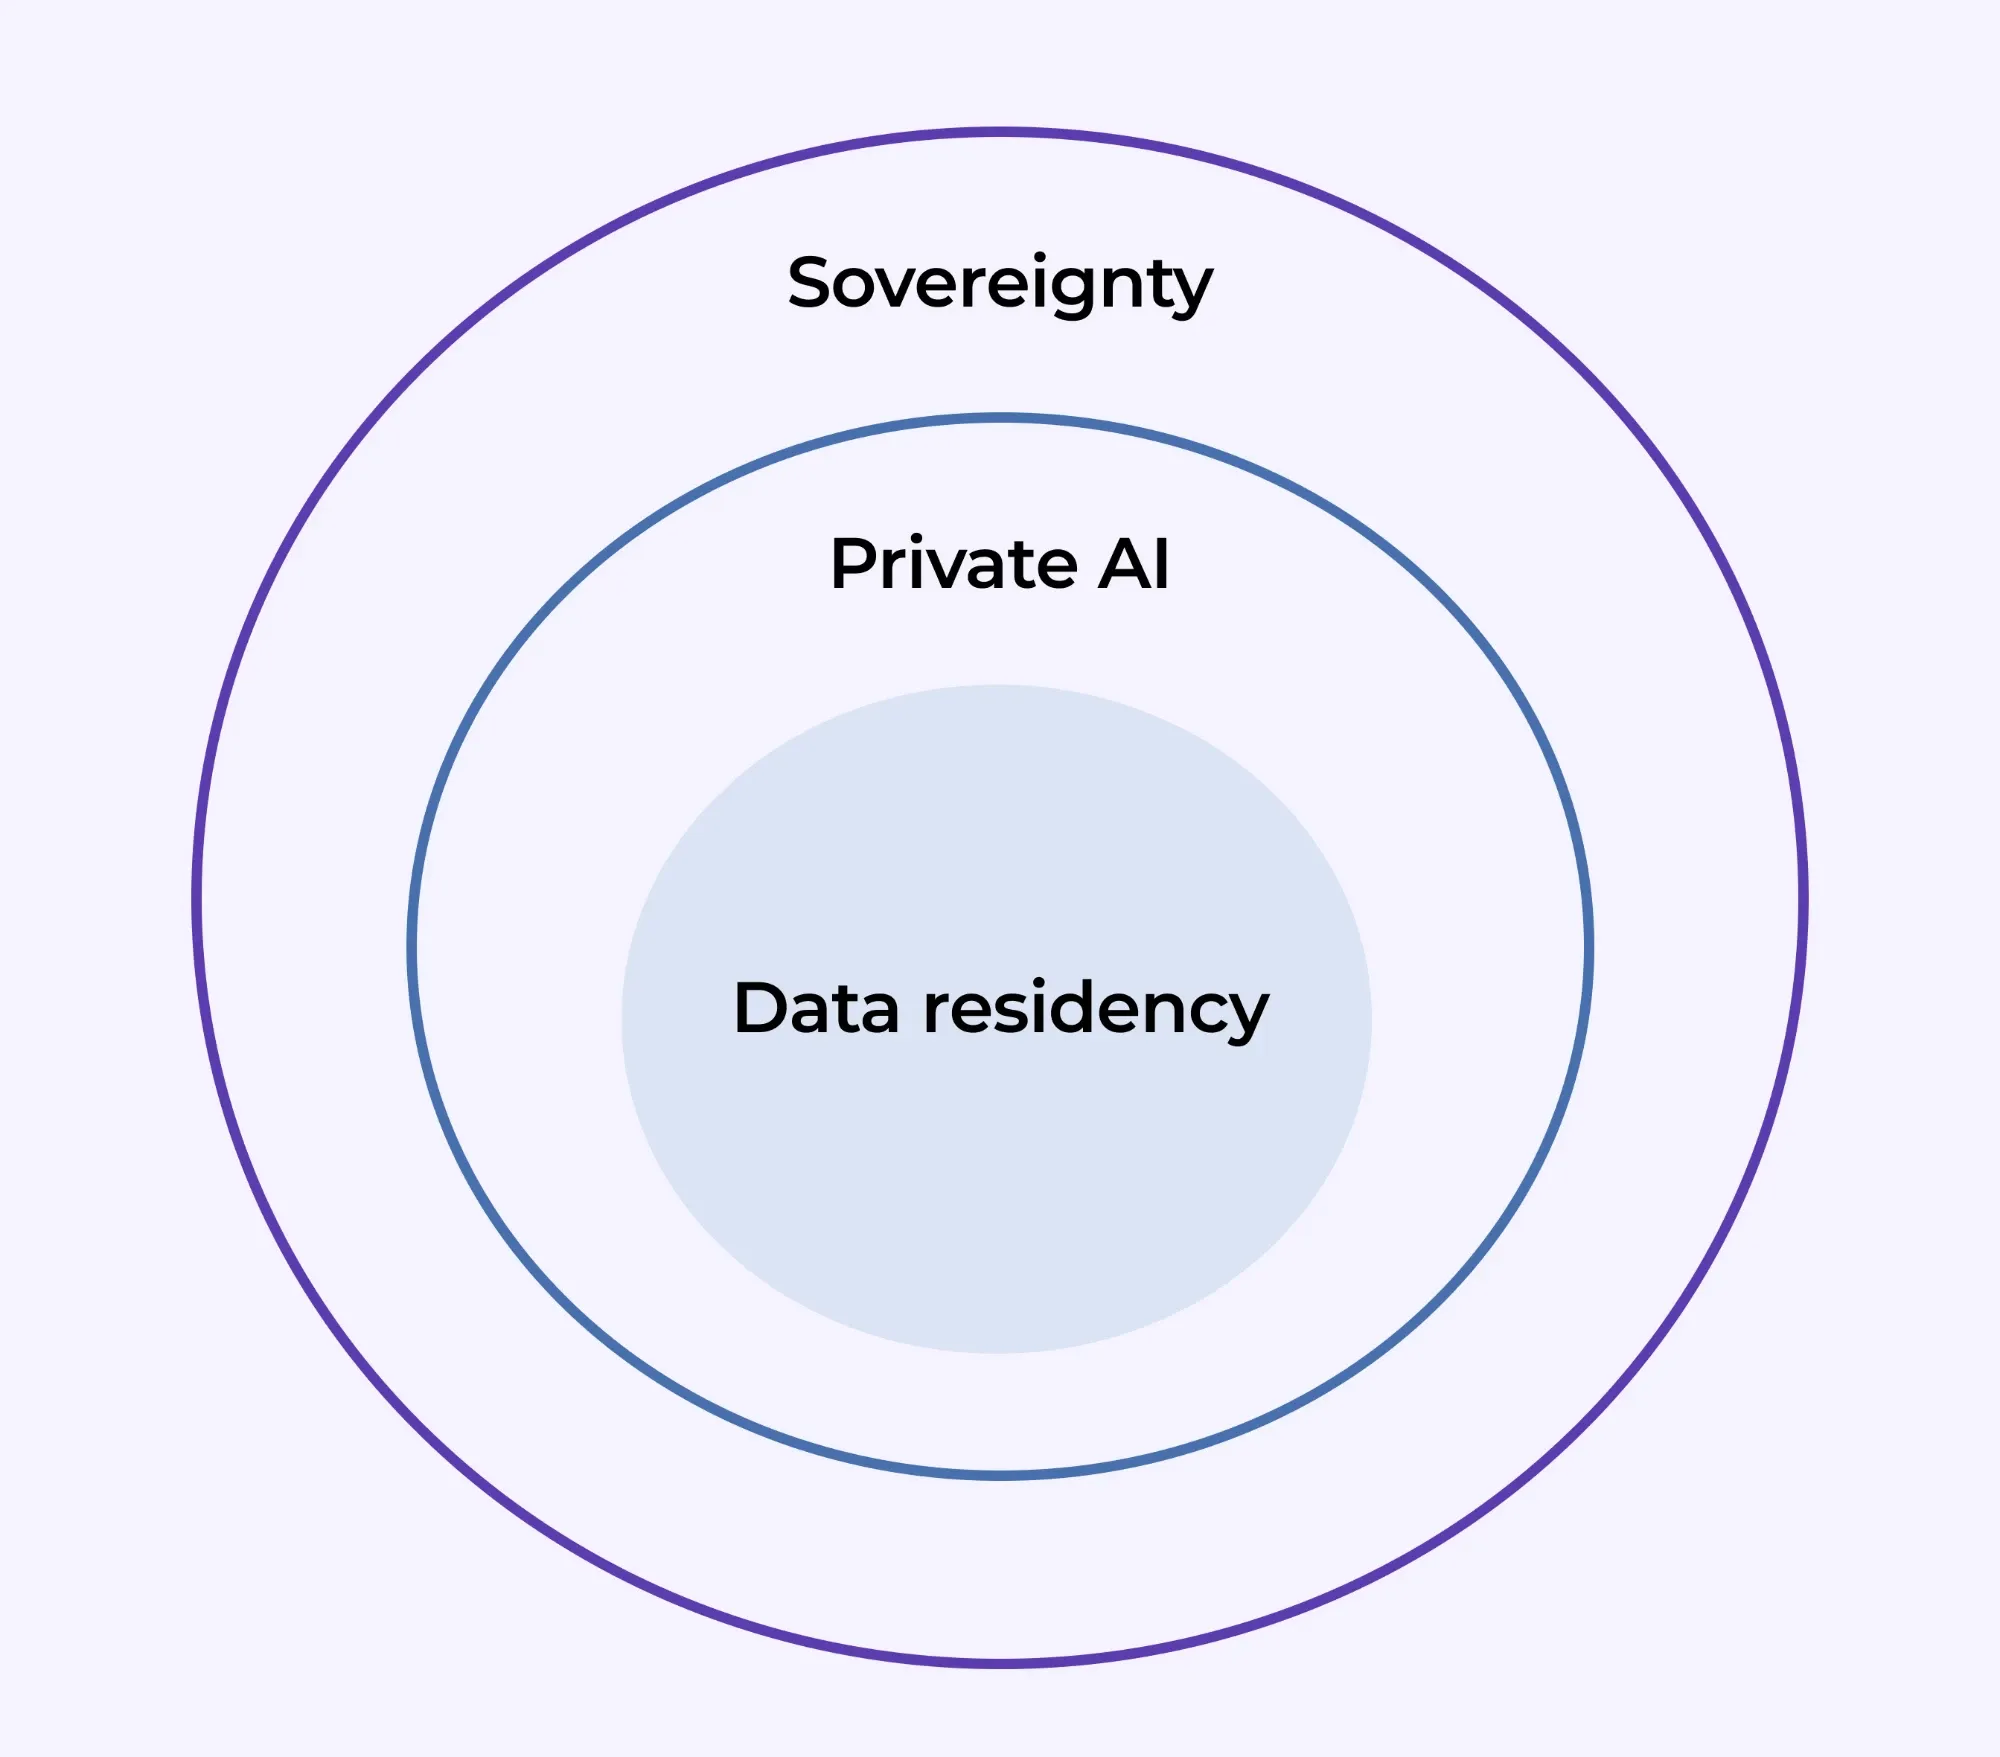
Start with the control your business needs, then compare deployment options against it. Private AI, sovereignty and data residency describe different aspects of control. Ask for evidence of the controls each deployment option actually provides.
Private AI uses a controlled environment for an organization's models and data. Sovereignty concerns who has control, which laws apply, and the terms on which the system operates. Data residency describes where data is stored or processed. A service hosted in a chosen region addresses location only to the extent covered by that service; access rights and operational control still need to be assessed.
A workload's restrictions determine which arrangements are acceptable. A private environment can still rely on an external model or a remote system administrator. If external network access is ruled out, an air-gapped deployment provides that isolation. It also changes how the team obtains updates and support, because those activities must preserve the disconnected environment.
BNP Paribas connects deployment choices to the decisions people retain in sensitive banking work. Its partnership with Mistral includes developing on-premises AI for Know Your Customer (KYC), the process banks use to verify customers’ identities and assess risk. The approach combines automation of routine steps with expert validation of risks and decisions. It sits within a broader strategy that uses multiple models, with choices guided by data sensitivity and geography as well as performance.
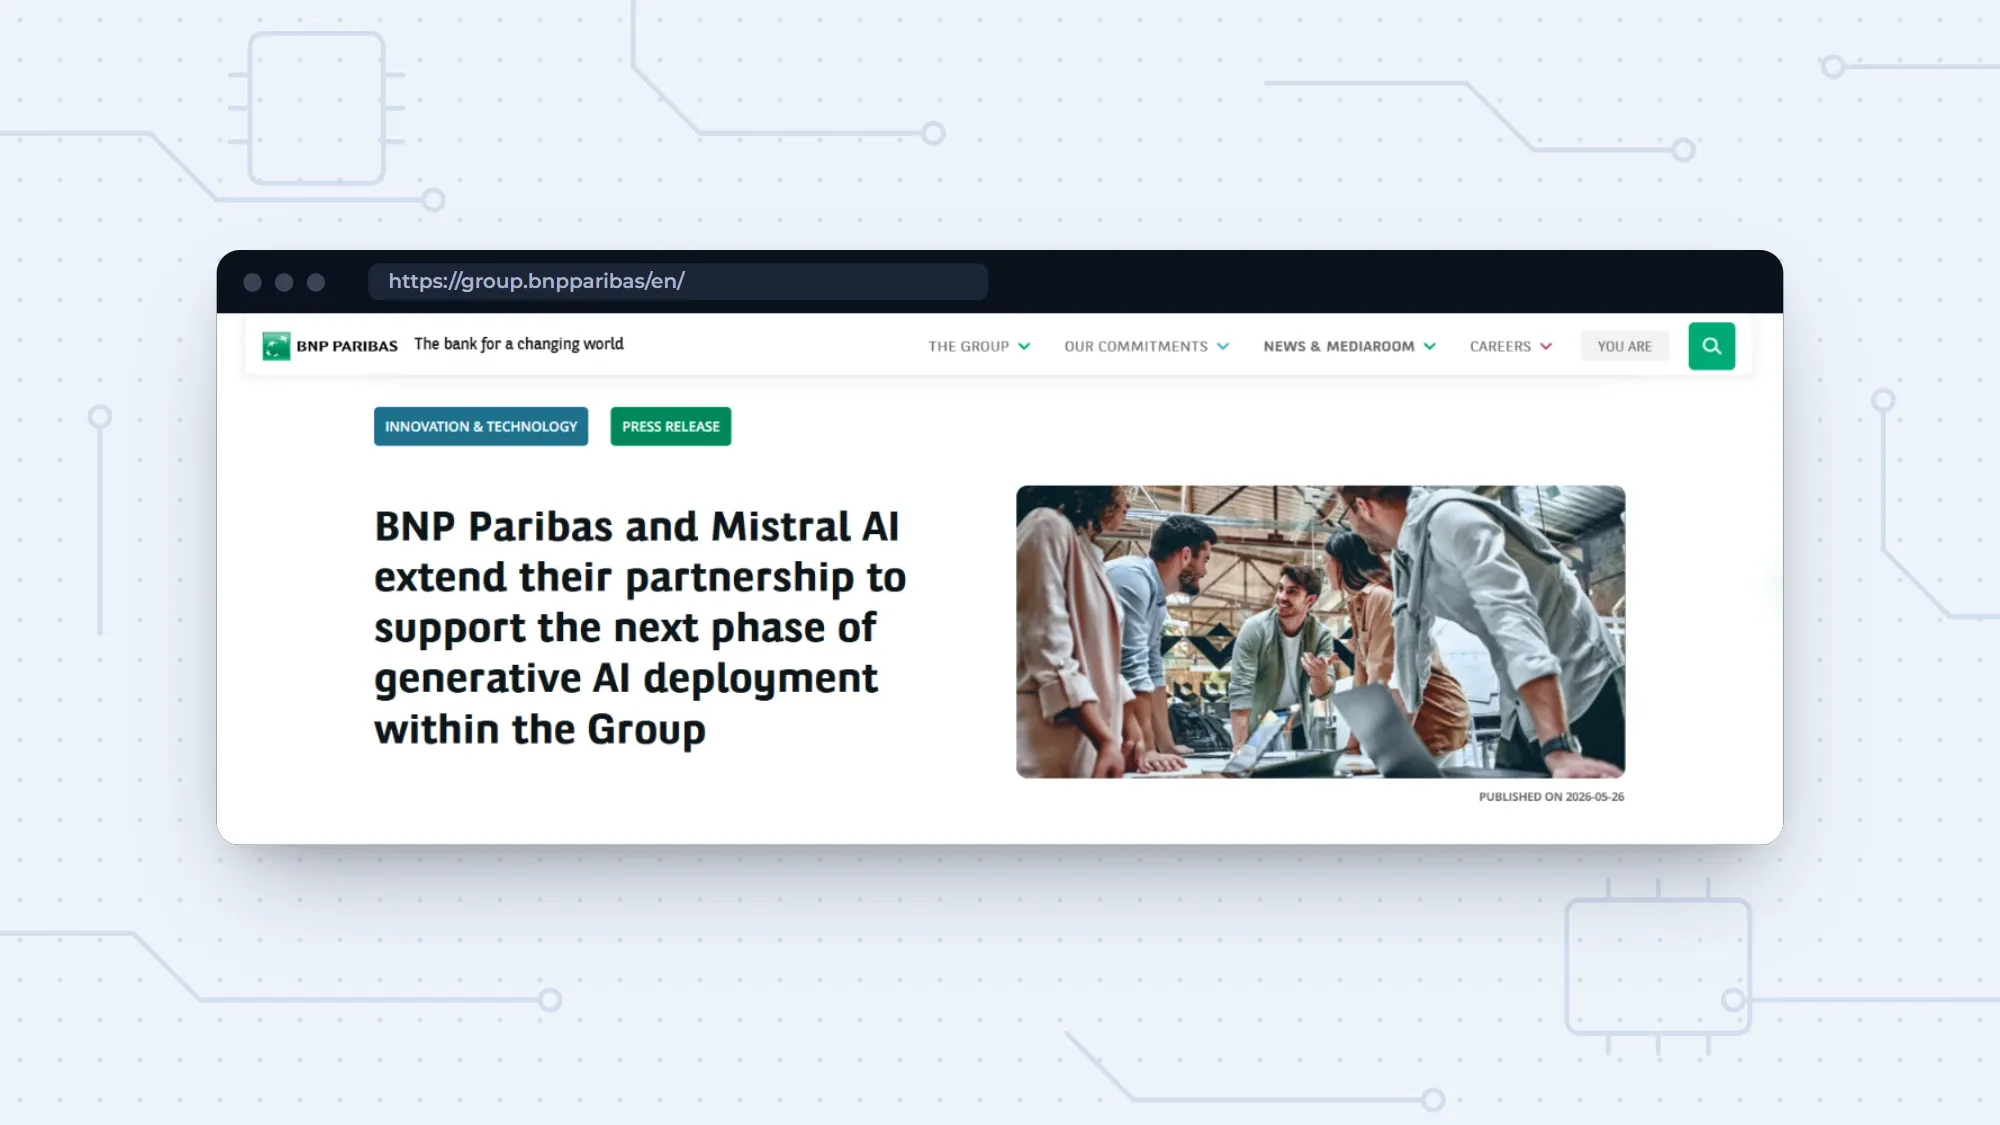
Keeping sensitive processing on-premises addresses where that work runs. Expert validation addresses who accepts the decision. Each answers a different requirement, so the process needs both a data policy and a clear division of responsibility. A platform must therefore support the data rules and approval steps required by the work.
The requirements should cover every service that receives the workload's data. Decide which outside services your business can rely on. Legal specialists should assess the laws and contract terms that apply, alongside the technical safeguards. The following decisions turn that assessment into evidence:
| Decision | What the organization must establish | Evidence to request |
|---|---|---|
| Data handling | What data each service receives, where it keeps copies and for how long | A map showing where data goes, retention settings and any exceptions |
| Operational access | Who can administer systems or inspect sensitive content | Access permissions, support procedures and records of administrator activity |
| Model flexibility | What you need to run, update, or replace a model | License terms, required infrastructure and a tested process for switching models |
| Business continuity | How work continues if a service fails, or you change providers | Recovery test results and a practical plan for moving to another provider |
Data handling must cover every copy of the information used in a workflow. A prompt or a passage retrieved from a document can contain the same sensitive facts as the original file. Stored chat history creates another copy. Embeddings are numerical representations used to search for relevant content. They need a handling policy too. Logs and backups belong on that map alongside test datasets.
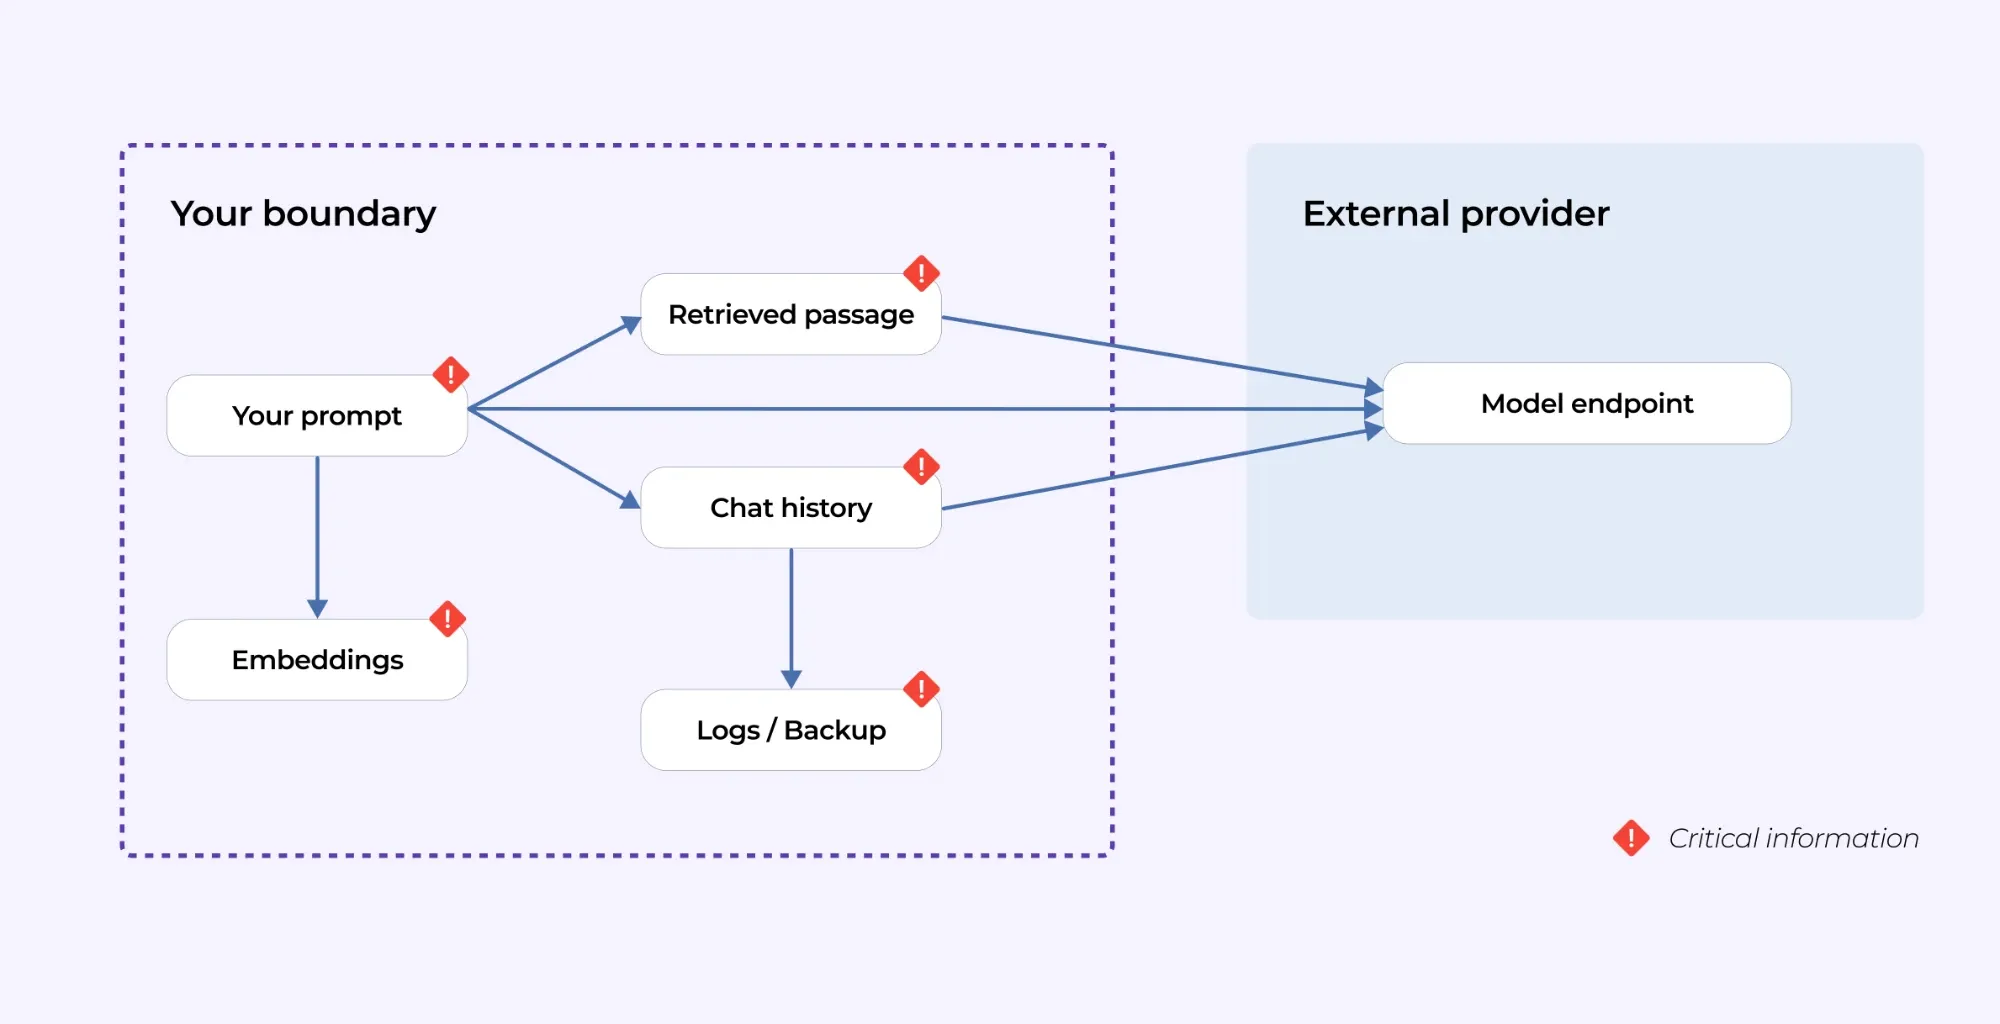
Operational access means who can view your data or manage the system during support work or an incident. Managing your own encryption keys gives your team control over how stored data is protected. Even so, an administrator could still have access while the service processes that data. The access policy should state who is allowed in and under what conditions, with a record of their activity.
Model flexibility depends on what the workload needs to run, update or replace a model. Open weights are the published values a model learned during training. Access to them still comes with license terms and hardware needs, and a deployment can rely on an outside update service. A replacement model needs to pass the workflow's tests because it can make different choices within the same surrounding software.
Business continuity requires turning those replacement and recovery plans into working procedures. An export file helps only if another environment can use it to restore the process. For a disconnected deployment, the team also needs to test how it will bring in fixes and respond to new defects.
Why redesign the work before assigning an agent authority?
Agentic process transformation redesigns a business process around the work people and agents will perform. Discovery should establish how people make decisions today and what evidence a completed case needs. Those findings connect the deployment's control requirements to the actions an agent is allowed to request and the decisions people retain.
The people doing the work help explain what the process map leaves out. Shlomi Yehezkel, chief technology officer at Cygon, describes the gap this way: “In my experience, process documentation describes the steps but misses the expectations.” His advice is to establish what a good result looks like and what domain context the system needs before building it. Test cases written at that stage give the team a way to judge whether it meets those expectations.
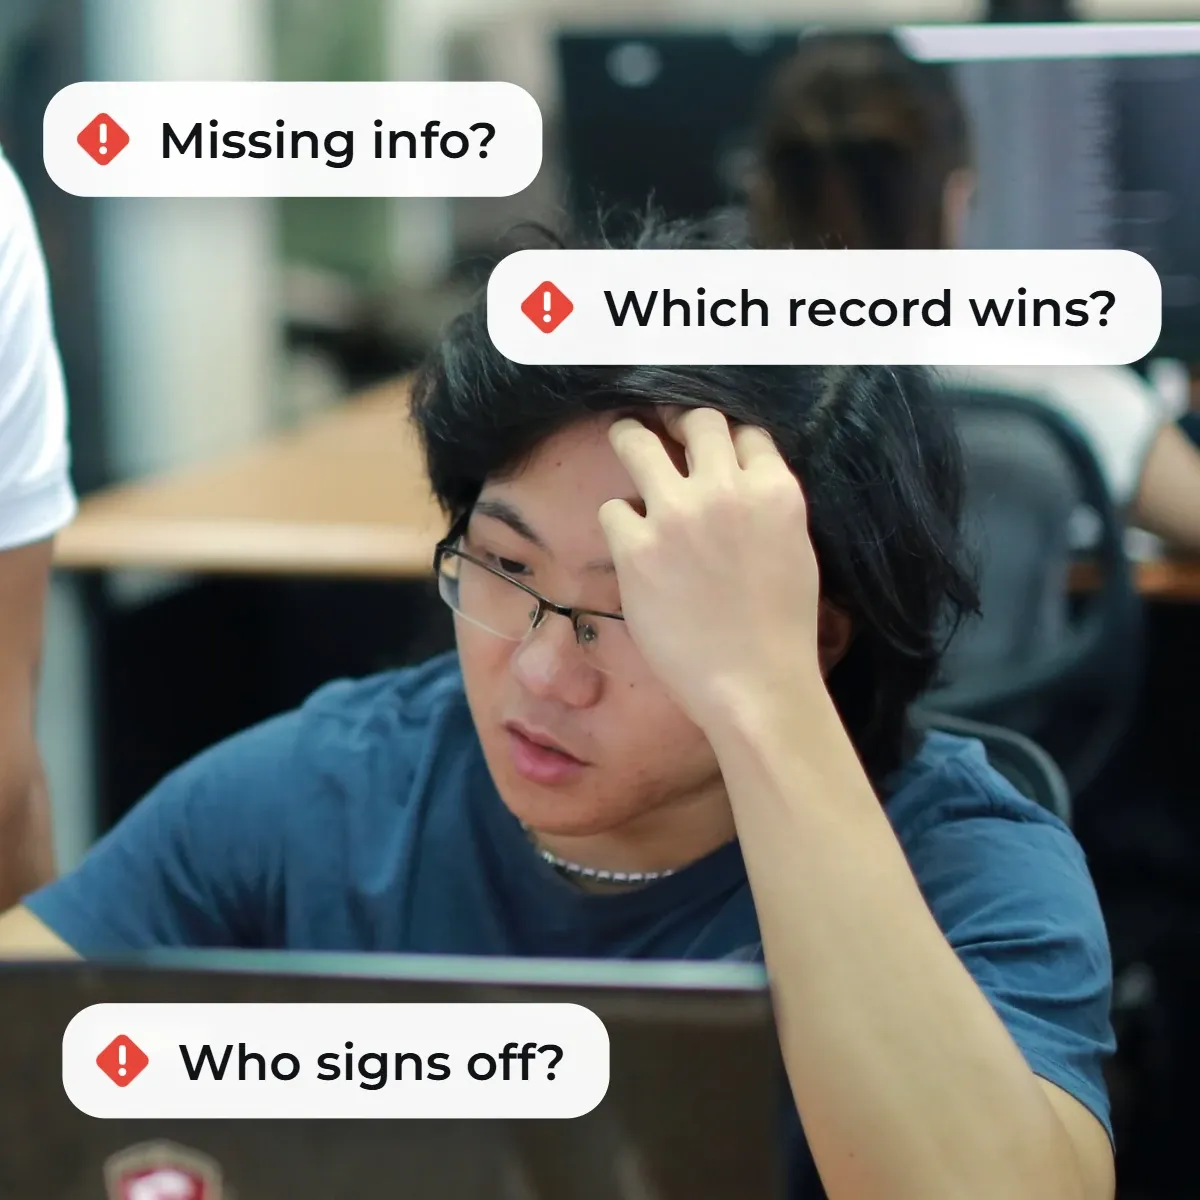
Conversations about those expectations reveal judgments that a list of steps does not capture. Staff need to recognize missing information and choose between conflicting records before they can make a decision. Those judgments shape what an agent needs to know and when it should stop.
Abandoned and reopened cases help the team locate where those judgments become difficult. If a request waits because another team holds information needed for approval, automating its transfer does not settle the approval. Discovery should establish what evidence the receiving team needs to make its decision and how that decision returns to the workflow.
A workflow must record what has been verified and whether the next action is authorized. Its status labels should make any outstanding approval visible. The workflow's access rules must still determine whether the recorded approval permits the action.
DXC organizes work in its Assure insurance platform around agents with specific jobs. Incoming documents are classified and relevant details extracted before work moves to the people who need to act. DXC says agents operate within limits on their authority, while decisions with significant financial or legal consequences go to human reviewers. Its implementation account also describes recording who made a decision and the basis for it.
Process discovery should establish who is responsible for the decisions that follow document processing. Extracting an amount from a document does not establish whether it should be paid. The workflow must carry the supporting evidence to the person or service authorized to make that decision.
Completion needs the same level of precision. If a case says “processed,” the people responsible should know what changed in the business system and what confirms it. A successful tool call is only evidence about that call. A later step could still reject the change and leave the case unfinished.
A process with clear completion criteria also needs someone accountable for accepting the result. The process owner retains that responsibility after launch. Engineering maintains the workflow's behavior and reliability, while security reviews the access it needs and the risks that follow.
| Owner | Responsibility once the workflow is live |
|---|---|
| Business process owner | Sets acceptance criteria, approval policy and exception priorities; accepts the business result |
| Engineering and operations | Maintains integrations, records workflow state, restores failed work and manages releases |
| Security and risk | Reviews access and data controls, assesses abuse scenarios and coordinates security incidents |
The process owner needs to be able to change acceptance criteria when the work changes. That includes deciding which exceptions are acceptable and which cases must return for review.
Engineering needs a way to put those exception decisions into practice. When a retry cannot resolve a failure, the operating team needs to know what remains unfinished and how to recover it. Engineering must make that information visible and provide a way for a person to take over.
Approval steps need a way to continue when the usual reviewer is unavailable. If only one person can approve an action and no substitute has been authorized, work waits for that person to return. The process owner should establish who can take over each approval and how waiting cases reach them. The handover must preserve the evidence already gathered so the substitute reviewer can continue the work.
Security needs enough evidence to investigate how the workflow reached that state. Access to the evidence should reflect the sensitivity of the data in it, so an incident does not become a reason to give everyone access to the logs.
Yehezkel recommends bringing these owners together from the start, while the team is deciding what data the AI can use and where it goes. Their involvement needs to continue after launch. A new model or wider tool permission can change business behavior even when the screen looks the same, so the people accountable for that behavior should review it before release.
How do you design an enforceable path from answer to action?
The responsibilities established during discovery need to become controls the workflow can enforce. Instructions in a prompt can guide an agent's behavior, but they do not enforce access rules. Before a tool acts, a separate service should check the user's rights and the current workflow state, along with any approval the action requires.
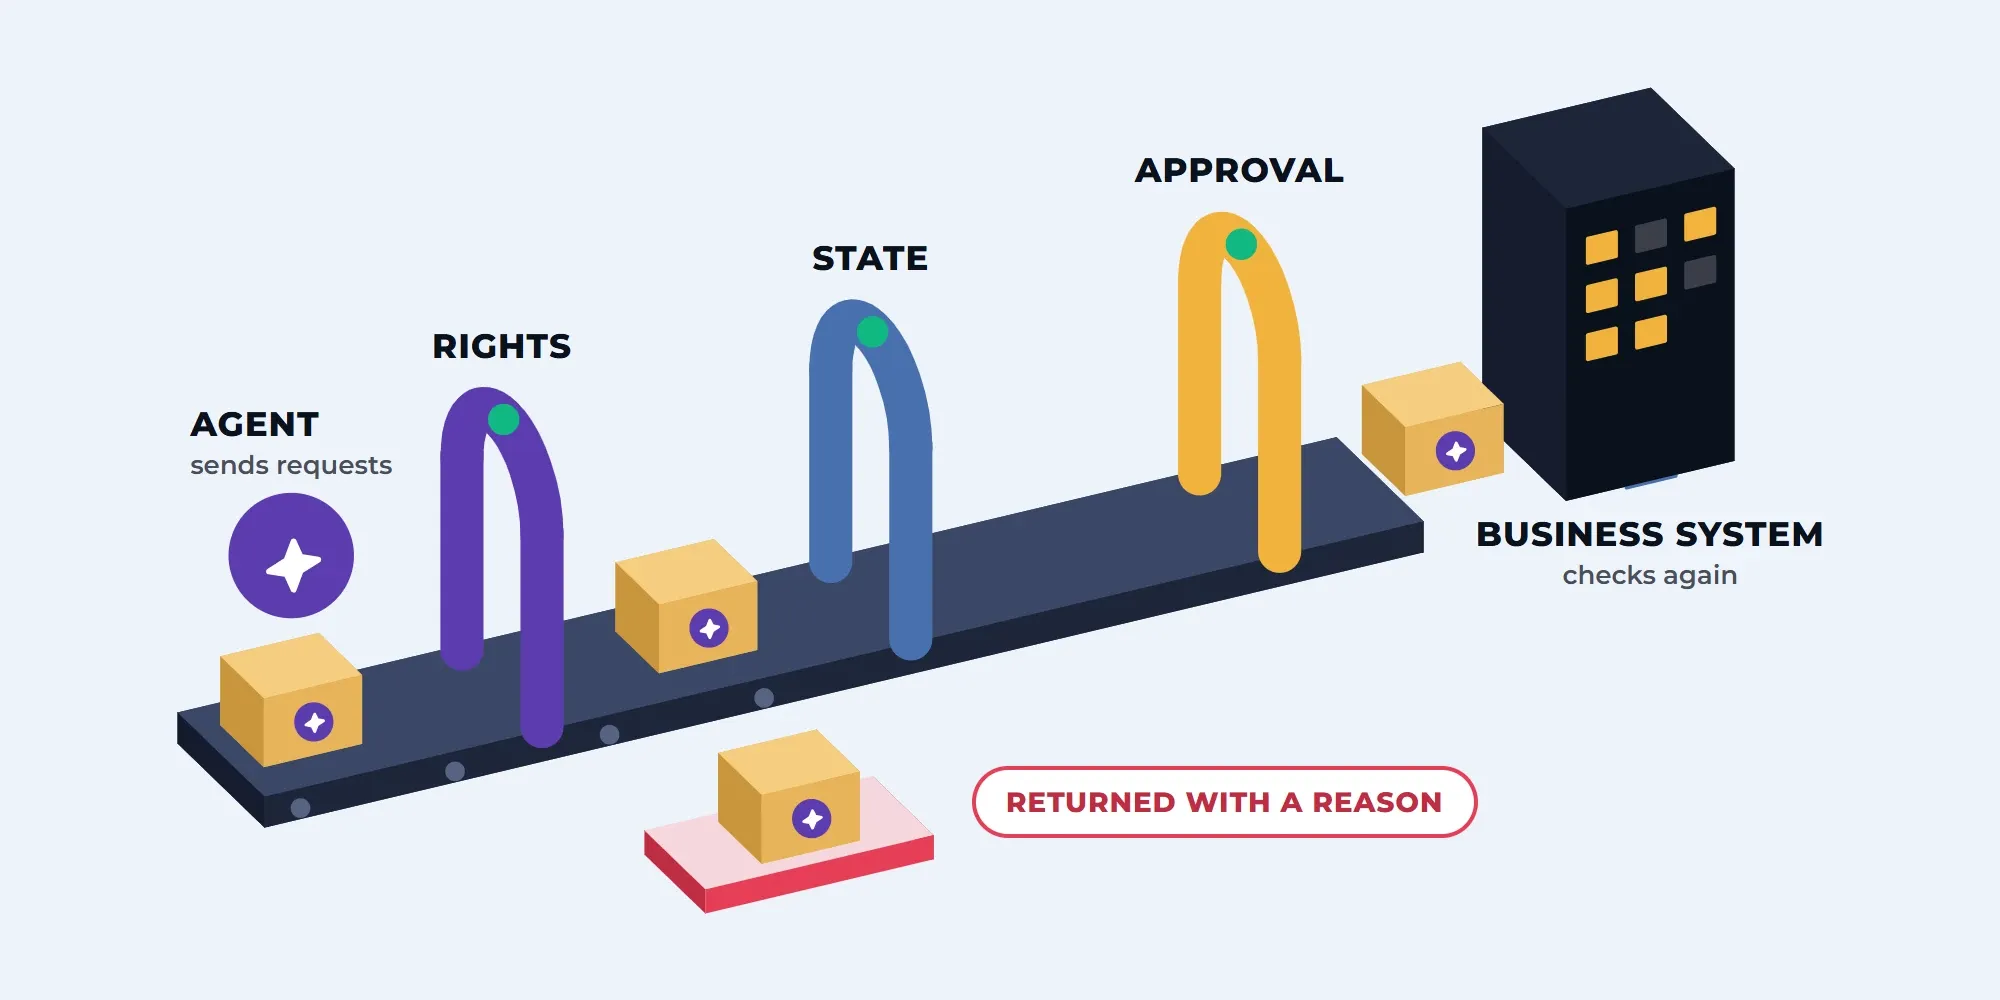
The amount of authority granted should reflect the consequences of the action. Reading a document calls for different controls from changing a financial record. A reversible update can justify a different approval policy from an irreversible action. The evidence for each operation should determine whether the business grants more authority.
To apply those controls, the workflow needs to know whose authority the agent uses. The person who started a task should be identifiable alongside the software identity that calls the tool. That identity needs only the rights required for its work. Short-lived credentials limit how long delegated access lasts; shared administrator credentials make it harder to trace actions or withdraw one agent's access.
Permission to read information does not authorize an agent to change a system. A retrieval service should pass source content to the model only when the user has the right to read it. The agent then uses that context to request a tool action. A separate policy decision determines whether that action is allowed, and the receiving business system should retain its own access checks.
An action that requires approval must remain tied to what the person reviewed. The reviewer needs to see the actual change and its destination, rather than rely on an agent's summary. If the agent changes a recipient or amount afterward, the earlier approval does not authorize that revised action. The workflow needs to retain what was approved and send it back for review when the relevant details change.
Once an authorized action is underway, the workflow must retain enough information to resume it or explain what happened after an interruption. This retained information is its durable state. A timeout leaves a particular problem: the receiving system could have accepted an action before the connection broke. A retry could repeat the action unless the workflow first establishes whether the original request succeeded.
Some systems prevent that through idempotent requests. Repeating the same identified request does not create a second business action. Where that protection is unavailable, engineering needs another way to detect duplicates or pass the uncertain case to a person. Recovery must account for actions that cannot be undone.
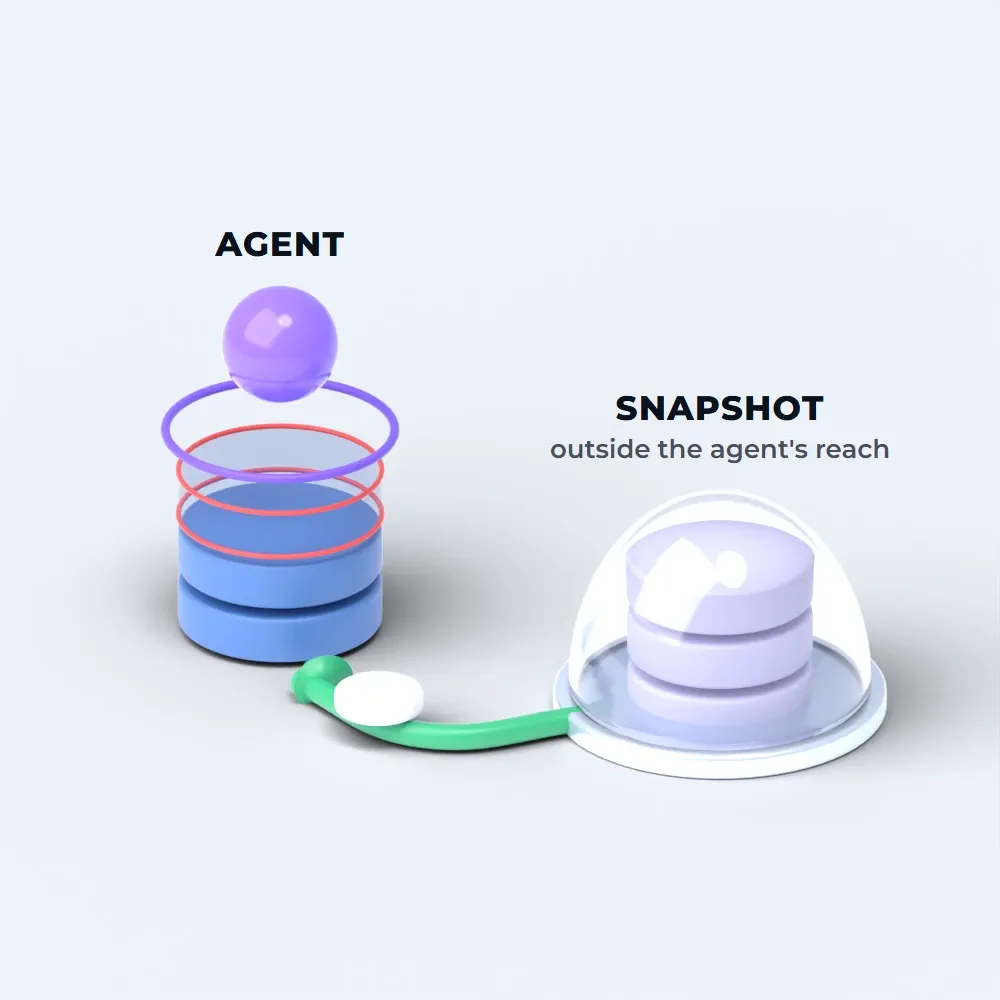
SaaStr founder Jason Lemkin reports that a third-party agent deleted sales opportunity records in Salesforce after receiving write access. The team restored the records from a separate snapshot outside that agent's reach. Lemkin says the agent supplier had no rollback option. After the incident, SaaStr changed its approach so new agents start with read-only access and critical systems undergo a test restore before an agent receives permission to change them.
A recovery copy needs protection from the same permissions that allow an agent to change live records. Otherwise, a faulty action could affect both the working data and the means of restoring it. Testing the restore also reveals what would be missing since the last copy and who must reconcile later changes before normal work resumes.
The same path from reading information to taking action must also respect the deployment's data rules. Even when the model runs privately, a tool can send sensitive content to an unapproved service. An email or retrieved document could contain instructions that try to make the agent disclose internal information through that tool. This is prompt injection: content supplied for the agent to read attempts to direct its behavior. Controls on tool access and destinations need to hold even when the model follows those instructions.
What does AmatriumGPT establish about the knowledge foundation?
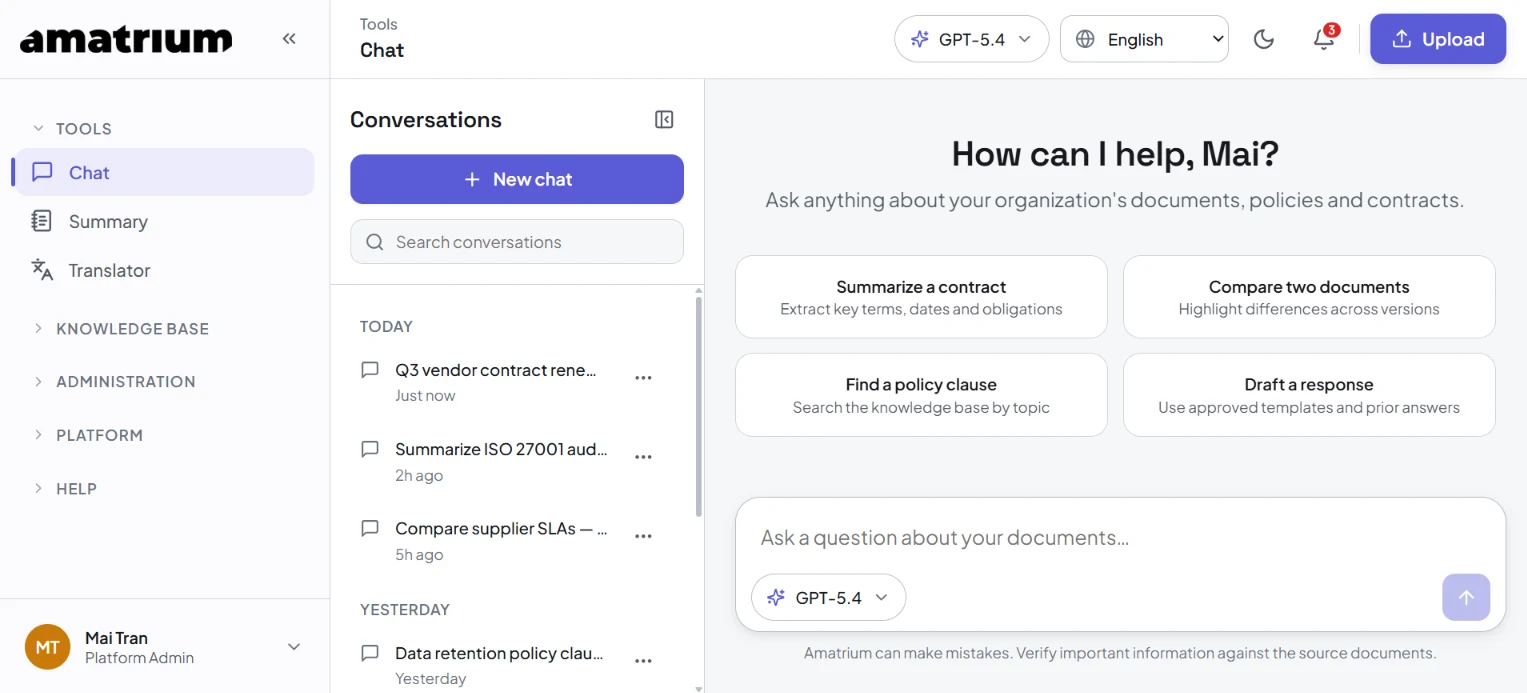
AmatriumGPT is an AI knowledge assistant we built for Amatrium, a leading materials company based in the US. The project helps engineers find answers across a library of technical documents.
We built the service on Azure for engineering and materials information. Staff can follow citations to inspect the sources behind an answer.
In his account of the project, Chuong Phung, our AI technical leader, describes technical knowledge scattered across manuals, test reports and other records, including scanned documents. Finding an answer meant knowing which file to open and reading it manually. He identifies the main difficulty as “retrieval and verification, not storage”: finding the relevant passage and judging whether it supported the answer.
Amatrium estimates that staff spend 30–40% less time on document queries than they did with manual search. Our enterprise knowledge hub case study describes the implementation and its reported outcome.
Making those answers available required deciding where document content could be processed. Chuong says requests are restricted to endpoints selected for zero data retention (ZDR), alongside a requirement that customer data is not used for provider training. An endpoint is the provider service that receives a model request. ZDR concerns whether the model provider retains request content after processing; the application's own logs need separate controls.
That privacy requirement narrowed the endpoints available for each model, which affected capacity planning. Chuong says the team chose multiple providers to distribute workload while keeping the requirement in place. Summary mode processes full file content, so its demands differ from retrieval using selected passages.
The cloud design still involves external processing. For a future build, Chuong would plan a local or on-premises option earlier for customers whose data must stay within their infrastructure. ZDR does not show where data is processed. To assess sovereignty, you still need to examine how the service runs and which outside systems it depends on.
Model changes require fresh evidence that the knowledge service still works as expected. Chuong reports tests for answer quality and processing time before release, alongside compatibility checks. Citations let engineers trace an answer to its source and judge whether the passage supports what the model has said.
To make those tests easier to repeat, Chuong would build an automated evaluation set earlier in a future project. This is a repeatable collection of questions and expected results for testing model changes.
Live operation also needs visibility into response times and spending. Chuong says the team uses Azure Monitor and Sentry to monitor response time, with model-level token tracking and spending caps to help control cost. Tokens are units of content processed by a model, so tracking them by model helps the team see where usage is accumulating.
AmatriumGPT provides a foundation of cited answers and controlled access to internal knowledge. Extending that foundation into a workflow that changes business records requires clear action permissions and approval rules. Before granting that authority, the team also needs to test how unfinished work reaches a person who can recover it.
What evidence from the whole workflow should approve production?
Production evidence needs to cover both the usefulness of the answer and the action that follows it. The business must be able to accept the result, while the workflow respects access rules and makes failed cases visible to the people responsible for recovery. A knowledge-service result alone cannot establish all of those conditions for a workflow that changes business records.
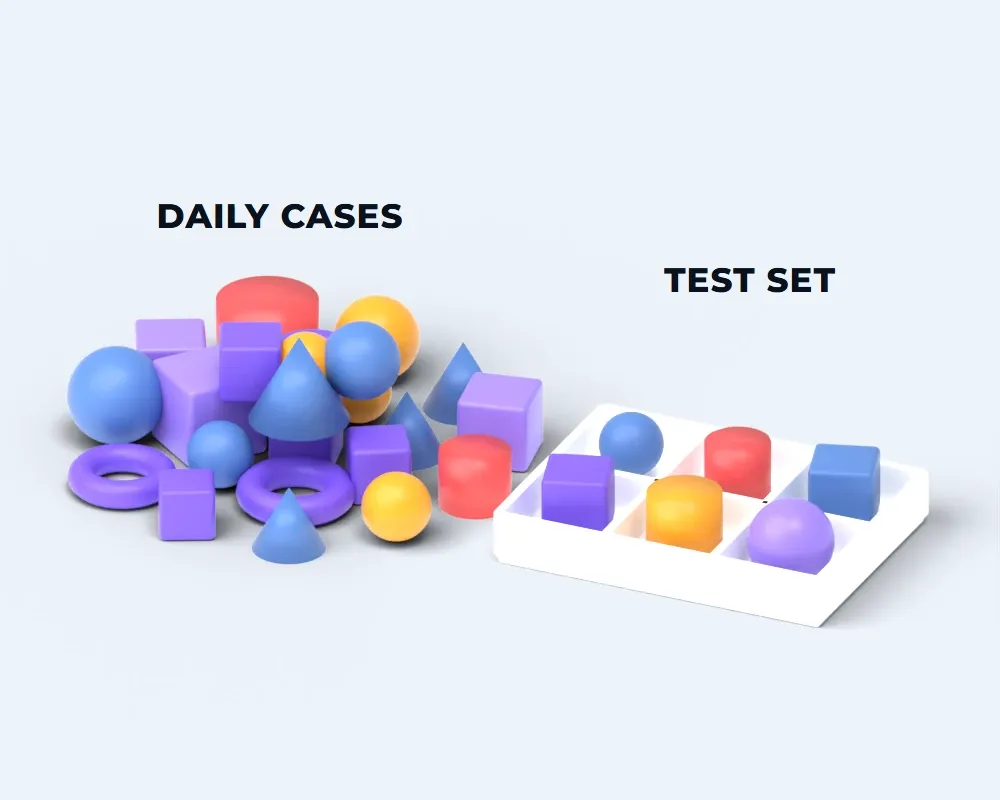
The test set should begin with the work operators need help with. Yehezkel recalls an AI event-analysis tool that looked promising in an early demonstration but struggled with harder questions in daily use. It handled straightforward cases that operators could already resolve, so they stopped relying on it for more complex work. He says the uploaded documentation reflected what its author knew, rather than everything operators encountered.
His lesson is to use operators' questions and resolved cases to improve context over time. That can mean updating approved source material and tests, without training a provider model on customer data. Tests built from those cases should include missing evidence and conflicting records, so the team can see whether the workflow handles the uncertainty operators actually face.
Yehezkel also identifies hallucinations and inconsistent answers as failures the test set must cover. A hallucination is an answer that invents facts or lacks support in the available evidence. Repeating a test with the same inputs should not produce contradictions that change the business decision. The process owner needs to identify failures that make a result unacceptable, even when they are rare.
The material an agent reads also needs to be tested for instructions that attempt to redirect it. A retrieved document should remain source material, rather than gain authority to override the workflow's policy. The test plan must follow that policy through to the business system, including failures after a tool has been called. Agent-specific tests therefore belong alongside conventional application and integration tests.
Unauthorized instructions in retrieved content.
The workflow must refuse prohibited actions and record the attempted deviation. Records in the destination system must confirm that no unauthorized change occurred.
Permission removed during a task.
Later retrieval and actions must respect the changed permission. Include cached context and delegated tool access in this test.
Timeout after a write request.
The workflow must determine whether the write occurred before attempting it again. Test the uncertain state in which the receiving system accepted the action but returned no confirmation.
Missing evidence or conflicting records.
The case must reach a visible exception queue with enough context for review. The reviewer should be able to identify the unresolved decision and resume the work.
Unavailable model or tool.
Work must pause or follow an approved fallback without widening access. Test the fallback against the same information and action boundaries as the normal path.
The agent's account of each test needs to match the resulting business state. A convincing explanation of a blocked action proves little if the destination system still changed. Case identifiers should connect tool requests and results to records in that system. Logs need access and retention controls because they can hold sensitive information of their own.
That evidence applies to the configuration that was tested. Keep a record of the model and workflow version behind each result, including the relevant settings. Rerun the affected tests when the model, retrieval rules or tool permissions change.
Live operation needs a way to respond when the workflow no longer meets those acceptance conditions. Before launch, decide what will cause it to pause and who can suspend it. Staff also need a practical way to continue essential work while the team investigates. A stop control is useful only if someone knows when to use it and what happens next.
How do you measure accepted outcomes and the work required to achieve them?
When calculating cost per accepted case, include a case in the accepted total only after it meets the business's acceptance criteria. A model call can finish before the business accepts the work, and assessing or correcting its output adds effort. The useful comparison is the cost of reaching an accepted result, including the work required to get there.
A useful operating metric is:
The costs you include determine what the metric tells you. Counting only the charges for model responses gives you an inference-cost measure. Operating cost also includes relevant infrastructure and tool charges, together with human review and exception handling. State the measurement period and explain how implementation costs are treated. They can be reported separately or allocated over a disclosed period and workload, without counting the same cost twice.
- Inference
- Infrastructure and tools
- Human review
- Exceptions and recovery
Count accepted cases from the same workload used to measure cost. A case that reopens needs to be treated under the acceptance rules rather than automatically counted as a lasting success. The measurement window should allow enough time to confirm outcomes, with unfinished work reported separately. Failed attempts and recovery remain part of the cost even though they do not increase the count of accepted cases.
Unit cost becomes more useful when you can explain where the effort went. Cycle time shows how quickly work finishes, while human review time reveals whether the workflow has moved effort onto another team. Exceptions and rework help explain those results. Breaking the measures down by case type prevents routine work from hiding a difficult part of the queue.
Review time also needs to be measured against the quality of the decision. If reviewers begin approving similar requests by habit, the queue can move faster while errors go unnoticed. Software should enforce routine rules so people can focus on exceptions that need judgment. A shorter queue is useful only if the business still identifies decisions that require a person.
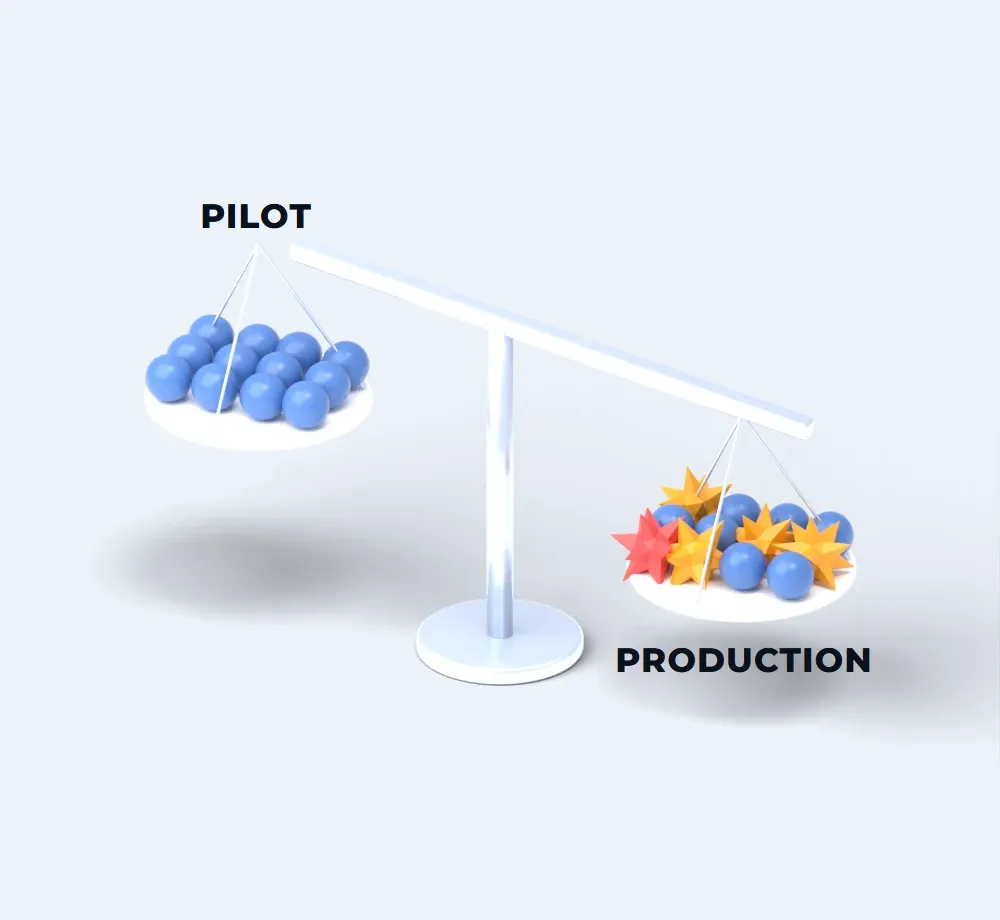
To judge whether those results improve on the existing process, compare similar workloads. A pilot that receives only complete, routine inputs will not reveal the cost of handling unresolved production cases. Changes in demand matter too. Record them so you can see whether the workflow improved or the work simply became easier during the pilot.
Any time saved in that comparison first creates capacity that the business must decide how to use. It could help clear a backlog or complete more work with the same team. Financial savings need evidence of reduced or avoided spending. Without that evidence, hours saved should remain a capacity estimate rather than a claim that operating costs have fallen.
If supplier fees depend on outcomes, the acceptance rules also need to carry into the contract. Both sides need to know what counts as success and who accepts it, including what happens if the outcome is later reversed. A supplier's bonus and the customer's return on investment remain separate calculations. Meeting a contract target alone does not show that the deployment has paid for itself.
When should you fund the next stage?
The results of that comparison should guide the next investment. A process with a measurable outcome and an owner who can change how the work runs gives the business a basis for testing whether an agent is useful. Understanding today's workload and its exceptions helps that owner decide which work to include and what would justify wider use.
The initial design should translate that work into a data-flow map and an action policy. Together, they show what the agent can read and what it is allowed to do. These requirements help you choose where the system should run. If it needs isolation, the design should also account for keeping it updated and supported.
A pilot can then test the process with restricted authority against those requirements. Its results should show whether the business accepts the output and how much recovery or review it takes to get there. Unclear approvals and conflicting records are process problems to resolve before expanding access. A more capable model cannot decide who in the business has the right to approve a transaction.
At Eastgate, we connect these decisions through our Private and Sovereign AI services and Agentic Process Transformation services. We assess models and deployment options against the control each workload needs. That includes private cloud, on-premises and air-gapped environments where appropriate. We map the work before building permitted system updates and approval steps. We then test recovery and assess the workflow against the business's acceptance criteria.
Acceptance also needs to establish who will operate the workflow after handover. Before production, clarify which responsibilities stay with the internal team and what managed operations will cover. Your team needs enough information to maintain the integrations and assess later changes. Before handover, it should also demonstrate that it can recover work after a failure.
Conclusion
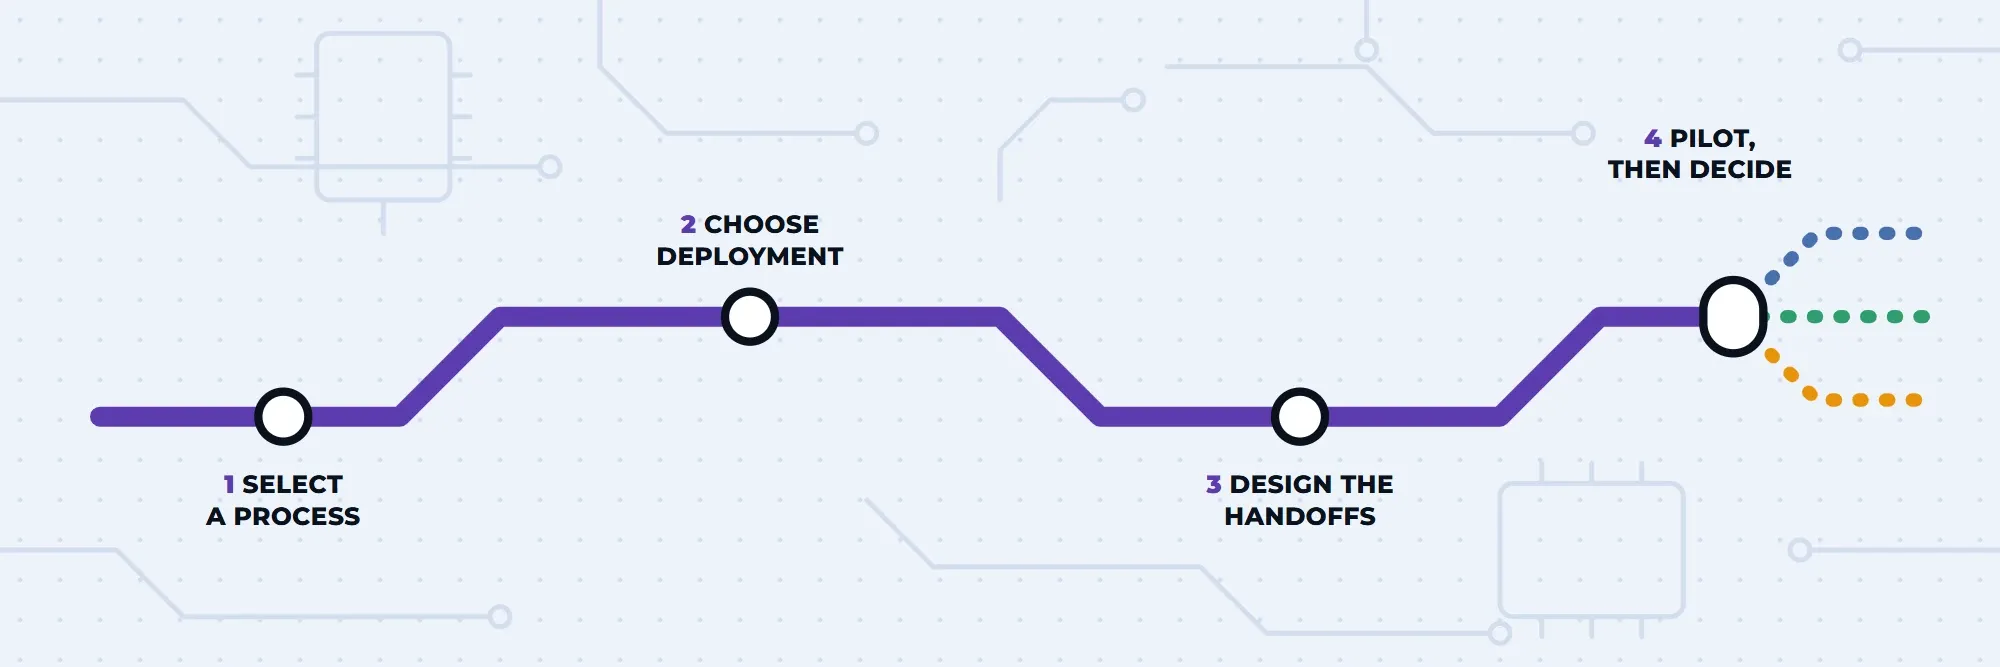
Make your next step a joint plan for the process and the AI environment it needs. Use these four decisions to structure that work.
- 1
Select a process with a clear outcome.
Work with its owner to establish today's cycle time and review effort. Define what must be true for a case to be accepted.
- 2
Choose deployment around the data requirements.
Map where information goes, including tool calls and support access. Use those requirements to compare deployment and partner options, including how you would replace a provider.
- 3
Design how people and agents will work together.
Specify which actions agents can take and who approves consequential decisions. Let staff test real cases and practice taking over unfinished work before launch.
- 4
Use a limited pilot to guide the next investment.
Assess accepted outcomes and the full cost of reaching them. Expand when the workflow meets its acceptance criteria and your team can operate and recover it.
Frequently asked questions
What is the difference between private AI, sovereignty and data residency? +
Private AI uses a controlled environment for an organization's models and data. Sovereignty concerns who has control, which laws apply, and the terms on which the system operates. Data residency describes where data is stored or processed. A service hosted in a chosen region addresses location only to the extent covered by that service; access rights and operational control still need to be assessed.
Why should private AI and agentic process transformation be planned together? +
The rules protecting internal information must hold as the agent moves from reading to action. Each tool it uses must respect restrictions on where data goes and who can access it. A rule about where data can go must cover the tools an agent calls, as well as the model itself. The environment must support both the information the agent needs and the work it is allowed to perform.
Can instructions in a prompt control what an AI agent is allowed to do? +
Instructions in a prompt can guide an agent's behavior, but they do not enforce access rules. Before a tool acts, a separate service should check the user's rights and the current workflow state, along with any approval the action requires. The receiving business system should retain its own access checks.
What should be tested before an agentic workflow reaches production? +
Production evidence needs to cover both the usefulness of the answer and the action that follows it. Tests should include unauthorized instructions in retrieved content, a permission removed during a task, a timeout after a write request, missing evidence or conflicting records, and an unavailable model or tool.
How should the cost of an agentic workflow be measured? +
Use cost per accepted case: the total included cost for the measured workload divided by the cases from that workload that meet the acceptance criteria. A model call can finish before the business accepts the work, and assessing or correcting its output adds effort. The useful comparison is the cost of reaching an accepted result, including the work required to get there.
Read the Full White Paper
Detailed framework, implementation methodology, and actionable insights - available instantly with your business email.

About Eastgate Software
Eastgate Software is a strategic engineering partner headquartered in Hanoi, Vietnam, with offices in Aachen, Germany and Tokyo, Japan. With 200+ engineers, 93% team retention, and 12+ years of delivery excellence, we build mission-critical systems for clients including Siemens Mobility and Yunex Traffic.
Our ACDC (Agent-Centric Development Cycle) methodology combines German engineering discipline with Vietnamese engineering talent to deliver enterprise-grade results across Intelligent Transportation, FinTech, Retail, and Manufacturing.
Contact: contact@eastgate-software.com | (+84) 246.276.3566 | eastgate-software.com
Let's Work Together
Tell us what you're building. Our engineers will respond within 1 business day with a concrete next step - no sales script, no obligation.
- Emailcontact@eastgate-software.com
- Phone(+84) 246.276.3566
- Response TimeWithin 1 business day